Vision Transformers Market Summary
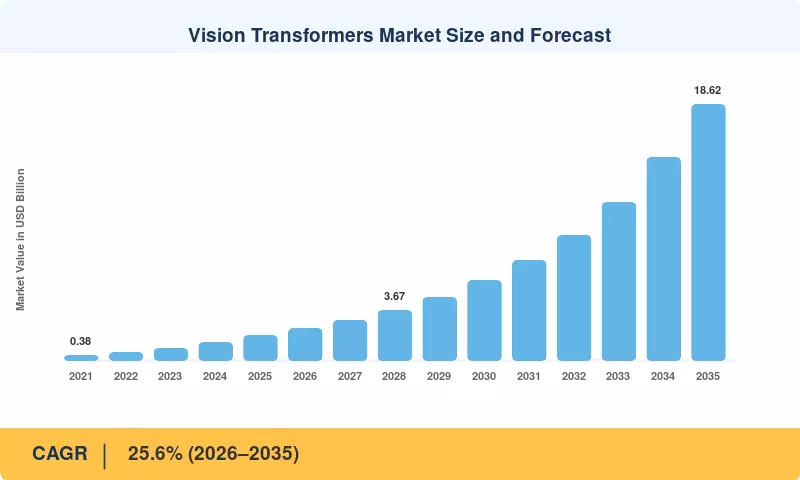
The Vision Transformers Market closed 2025 at approximately USD 1.84 billion and enters the forecast window at roughly USD 2.31 billion in 2026, climbing to USD 18.62 billion by 2035 at a 25.6% compound annual rate. Two catalysts anchor that trajectory. The EU AI Act, which entered into force in August 2024 with high-risk obligations phasing in through 2026–2027, forces auditability into perception pipelines — and attention-based architectures expose interpretable maps that convolutional stacks do not. Separately, the US CHIPS and Science Act committed USD 52.7 billion toward domestic semiconductor capacity, lowering the cost floor for the accelerator hardware these models demand. The Vision Transformers Market therefore grows on both a regulatory and a silicon tailwind.
The genuine narrative is that of replacement. Attention-based encoders are replacing the ResNet-family convolutional backbones, which have been the dominant technology in production vision systems since 2015. These encoders are capable of scaling predictably with data volume. The most credible estimates indicate that enterprise spending on AI infrastructure exceeded USD 200 billion globally in 2025. A growing portion of this expenditure is allocated to pretraining runs on billion-image corpora, which are only efficiently absorbed by transformer architectures. Rather than retrofitting, hospitals, insurers, and Tier-1 automotive suppliers are re-platforming.
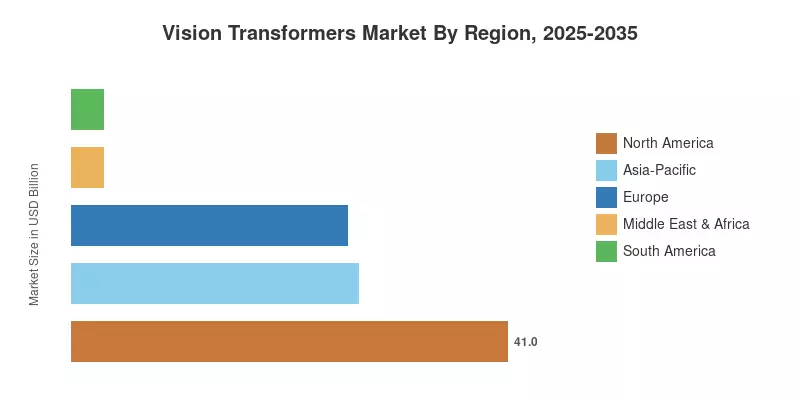
In 2025, North America is expected to account for approximately 41% of the Vision Transformers Market, which is bolstered by a concentrated foundation-model startup base and hyperscaler R&D. China's national compute buildout and Japanese factory automation retrofits are the primary factors driving Asia-Pacific's rapid expansion at a compound annual growth rate (CAGR) of 29.4% through 2035. Europe is the second largest market, with an estimated 26% share. Adoption is driven by regulatory clarity rather than raw compute. Vendors who develop these models at a low cost for peripheral operation will be rewarded in the coming decade.
Key Report Takeaways
• By Architecture
- Encoder-only architectures command roughly 44% of the Vision Transformers Market in 2025, reflecting their entrenchment in classification and retrieval workloads.
- Hierarchical and windowed designs post the strongest technology-level growth at 28.9% CAGR, driven by dense-prediction demand.
- Hybrid convolution-attention backbones generated approximately USD 0.41 billion in 2025 as a pragmatic bridge for latency-bound deployments.
• By End users
- Automotive and mobility applications account for about 23% of Vision Transformers Market revenue, the largest single vertical.
- Healthcare and diagnostics grows at 30.1% CAGR, the fastest vertical in the study.
- Industrial inspection and manufacturing contributed roughly USD 0.29 billion in 2025
• By Region
- North America leads with approximately 41% share of the Vision Transformers Market.
- Asia-Pacific advances at 29.4% CAGR, the fastest of any region
- Middle East & Africa reached roughly USD 0.06 billion in 2025 on sovereign AI programs
Market Size and Forecast (2021–2035)
Estimates blend bottom-up vendor revenue attribution, accelerator shipment data cross-checked against foundry disclosures, published enterprise AI spending surveys, and interviews with deployment engineers at 40-plus adopting organizations. Historical figures reflect commercial revenue only — academic compute and open-source contributions are excluded from the Vision Transformers Market baseline.




 Noah Malgeri
Co-Founder

 Peter Groot koerkamp
Account and Business Manager

 Younghwan Choi
Senior Retail Manager

 Mark Irwin
Management Consultant

 Akif Moroglu
Strategy & Business Development Director

 Guilherme Gomes Martins
Product Management Director

 Joseph Aguayo
Sales Operations & Pricing Manager

 La Terria Dodd
Program Support Specialist

 Rob Kooiker
Group Product Manager HVAC & Fire Protection GMA



